One Requirement, Three Different Builds: Read It, Tap It, Or Give Up
The requirement was one sentence. I wanted to handle a verification prompt landing on a phone that isn’t in my hand, from the screen I’m already looking at.
Reading that sentence, I pictured one automation. Something that catches a notification and forwards it somewhere, and I’m done. What came out was three builds that share no code at all, and the third one was blocked on the device and capture path I tested.
The split had nothing to do with what the notification said. It came down to whether I only have to read it, whether I have to tap it, or whether the OS refuses to hand over the pixels. Those three sit on different permission layers, so none of the code overlaps.
My first attempt burned 3.25 seconds on every single frame and I threw it away. In the second I fixed four bugs and the screen stayed black, and that black screen wasn’t my bug.
What the three branches are
The notifications I wanted to handle came in three shapes.
- Read and done — a few digits arrive as a text message, and looking at them finishes the job.
- Tap and done — an app puts up “approve this sign-in?”, and a person has to press the button on that screen. Reading the text accomplishes nothing.
- Blocked by the OS — the display is clearly on, and a capture taken with shell permissions comes back as a solid black rectangle.
All three get written down as the same sentence: handle a notification remotely. The builds are a notification listener, a video stream, and giving up.
| Branch | What it actually needs | What I used | Status |
|---|---|---|---|
| ① Read | One line of notification text | Notification listener + chat webhook | Verified end-to-end on a real device |
| ② Tap | Screen pixels + input injection | ADB H.264 stream → browser decode → tap coordinates mapped back | Verified on a real device (unlocked state only) |
| ③ Blocked | Lock screen pixels | Nothing | Blocked on the tested device/capture path |
① Read and done — this one was cheap
Android exposes notification events through NotificationListenerService after the user grants notification access. The listener receives the content the OS and app expose to it; redaction and other restrictions can limit what is available. Permission doesn’t guarantee that every notification’s full text will be visible.
So I wrote an Android app. It does three things. It receives text and messenger notifications, it filters for verification-code shapes with a regex whitelist and blacklist, and it throws the match at a chat webhook. The filtering living on the device is the part that matters. Only matched notifications leave, and everything else never departs that phone.
Approval-style two-factor notifications land in the same listener. I confirmed that on my secondary phone. Which package name that app sends its notifications under was a guess I put in and then corrected against the real device. The string came out of code generation looking entirely plausible, and plausible and correct are different things.
This part took a single day. Design through on-device verification, same day. So I assumed the rest would go the same way.
I don’t automate the approval tap — and that’s why ② exists
Before ②, this hard rule. It’s the most important line in the project.
The approval tap never gets automated. Detecting the notification and sending it to me is automatic. Pressing the approve button is always a person.
The reason is simple. Two-factor exists so that a human confirms one more time. Auto-tapping approvals means my own sign-in gets approved, and a stranger’s attempt on my account gets approved exactly the same way. The moment that automation goes in, two-factor is switched off.
Technically it was one line. The detection code already existed, and hitting a coordinate takes a single command. I left it out. The only thing worth bragging about in this post is the line I didn’t write.
That decision creates the next problem immediately. If a person has to press approve, that person has to see the screen. Moving the text over is useless. The pixels have to move. So ② stopped being a notification project and became a screen mirroring project.
② The one that needs a tap — my first build ran 3.25 seconds per frame
I started with the simplest thing. Capture the screen, send it as an image, repeat forever. It’s what anyone reaches for first when a remote screen is needed, and I reached for it too.
One frame took 3.25 seconds.
The bottleneck was transfer, not encoding. Dragging a multi-megabyte PNG per frame over wireless ADB is physically slow at the capture step itself. Shrinking it to JPEG after it arrives is already too late. Optimising the back end while the capture step is the bottleneck is wasted time. Dropping quality down to 540px wide changed nothing I could feel.
A 3.25-second screen makes “try pressing the approve button” meaningless. A screen that tells me what I pressed three seconds later isn’t remote control.
So I tore the whole thing out.
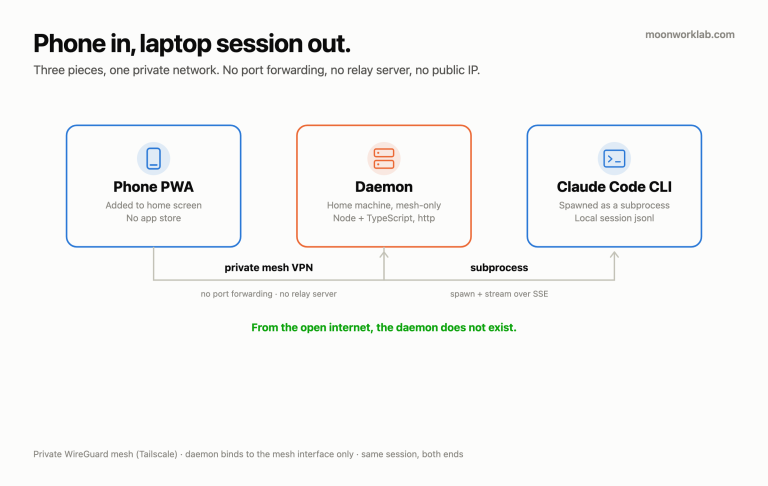
Android already ships a shell tool that emits the screen as H.264. On the build I tested, I used a long-running H.264 stream over standard output. The recording options and duration limits need checking on the target device. I take that stream, split it on NAL boundaries, build the decoder configuration record myself out of the SPS and PPS, and push it to the browser over server-sent events. The browser feeds it straight into VideoDecoder and paints the canvas.
Not one new dependency went in. No ffmpeg, no remuxing library. The NAL parsing is a few dozen lines of plain JavaScript, and the browser already owns an H.264 decoder, so there’s no reason to wrap anything in a container. That decision leaves the server side doing little more than relaying a pipe.
| Item | First build (screenshot polling) | Second build (H.264 stream) |
|---|---|---|
| Frame interval | ~3.25 s per frame (measured) | Real time |
| Transfer unit | Multi-MB PNG per frame | 2.5 Mbps configured, actual output around 1 Mbps |
| Stream width | 540px | 540px (same) |
| Server-side conversion | PNG → JPEG resample | None (NAL framing only) |
| Outcome | Discarded | In use today |
Taps flow the other way. The coordinates the browser sends are in the 540px space, so the server scales them to the device resolution and injects an input command. If the distance between press and release crosses a threshold, it becomes a swipe instead of a tap. That side was far simpler than moving the screen.
The four bugs that blocked me, in order
Every one of these was pinned down by a log line or an error string on a real device. The order matters, so here it is in order.
① Recording dies instantly on a sleeping screen.
When the phone sits in doze, the screen recording tool spits ERROR: INVALID_LAYER_STACK and dies on the spot. There’s a reason I was slow to find this. Screenshot capture works fine in the same state. The first build had been running happily and only the second one died, so my first suspect was my own NAL parser. The parser was fine. Sending a wake signal to the device before starting the stream ended it.
② Safari refuses to decode without a resolution.
I put the codec string and the configuration record into the decoder config and left the resolution out. Chrome ran it fine. Safari on iPhone threw “Decode failure” from the first keyframe. That configuration worked in my Chrome test and failed in my Safari test. Carrying the encoded resolution along in the config message fixed it.
③ The real root cause was the stream opening twice.
Block noise crawled over the picture and the decoder threw errors. The cause wasn’t the codec. Two streams open at once were sharing the same module-level global state. When two processes write the same buffer and the same SPS/PPS, the NAL stream interleaves, and no decoder on earth reads that.
There was already a check that said “clean up if one is active”. It didn’t work. Listing devices, querying the display ID and reading the screen size are all asynchronous, so a second call arriving in that window lets both of them observe “not active” and sail through. A textbook check-then-use race.
My existing flag check didn’t stop it. I used a generation counter. On entering the stream-start function I bump a global counter synchronously and remember that value as my generation. After every asynchronous section I check whether the global counter still equals my generation, and if it doesn’t, I back out quietly without spawning a process. That enforces one rule: only the most recent call survives. I check twice — right after the async section, and once more immediately before spawning.
④ The code that woke the device every 20 seconds was turning the screen off.
A dying recording after the screen sleeps meant I set a 20-second wake timer during a session. The symptom was a black screen and a lock screen flickering back and forth. I read it as sending a wake signal to an already-awake device, and changed it to query power state first and only send when the device is asleep. The symptom disappeared. Whether that signal behaves as a toggle like the power button, I never checked.
After all that, the screen should obviously have appeared. It didn’t.
③ The one the OS blocks — I fixed all four and the screen was still black
With four bugs dead, the lock screen was still completely black. So I ripped the streaming out and ran the simplest test there is. I took a single screenshot while the device was locked. Same black rectangle.
The standalone capture was black too. That moved the failure outside my streaming decoder. Android documents secure-window restrictions such as FLAG_SECURE, which are consistent with a protected capture surface. I didn’t inspect the manufacturer’s implementation, so I can’t attribute the lock-screen result to that one flag with certainty. I recorded the limitation and stopped trying to work around it.
This is the most expensive lesson in the project. I fixed four bugs while mistaking OS policy for my own bug. All four being genuine bugs is what made it a trap. The symptom shifted slightly every time, so I kept believing the next fix was the last one. The black screen never changed across all four.
The conclusion for this setup was practical. I couldn’t see the protected lock screen through the capture path I tested. Once a person unlocked the device, ordinary app screens mirrored and taps landed. I kept that human step in the workflow. I didn’t test every device or every remote-access mechanism.
I considered an iPhone route but never implemented it. An account-level mirroring design raised a broader privacy question than forwarding a selected notification, so I wrote it down and stopped. There are no iPhone device measurements in this post. That unbuilt plan mustn’t be read as evidence for the Android capture result.
A small diagnostic before building the whole pipeline
The test I should have started with was an ordinary, unlocked screen, followed by the lock screen on the same device. Compare a standalone capture with the stream before changing the decoder. If both are black only in the protected state, another round of NAL parsing changes won’t explain that observation.
For a repeatable report, I would record the Android release and security patch, lock state, capture method, exact error, and the browser version used for decoding. These commands read version information and the device’s recording help:
adb shell getprop ro.build.version.release
adb shell getprop ro.build.version.security_patch
adb shell screenrecord --help
These are suggested checks, not fresh benchmark results. I didn’t retain the exact OS patch and browser versions in the published record. That limits how precisely another person can match my setup. Recording options and duration limits also vary: I wouldn’t assume that --time-limit 0 works on another device without reading its help.
Android documents NotificationListenerService, secure-window capture restrictions, and the ADB screen-recording tool. Those references explain the APIs; they don’t establish what happened on every manufacturer’s lock screen. The browser configuration is described in the VideoDecoder reference.
I didn’t try to defeat a protected screen. The next step was a human unlocking the device, then testing an ordinary app screen again. The phone-access bridge article covers the surrounding remote-service setup; my CLI login incident is another case where a test inside the wrong context misled me.
The split was about permission layers
Here’s the summary. The axis that split the requirement wasn’t what the notification contained. It was the layer the OS is willing to hand over.
| Layer needed | Does Android give it | Price |
|---|---|---|
| Notification text | Yes (user permission required) | One app. The cheapest thing here |
| Screen pixels + input | Yes (developer options + debugging connection) | An entire video pipeline. Four bugs |
| Lock screen pixels | Blocked in this test | A person unlocks the tested device |
This is why “can’t one automation cover all of it” is wrong. The three requirements read as one sentence to a human, and to the OS they’re three separate permission requests. The third request was refused on my tested capture path.
Don’t do these
Every one of these is something I did.
- Don’t design “I want notifications remotely” as one lump of a requirement. Read, tap and blocked sit on different permission layers, and none of the code overlaps. I started out assuming one build would cover it.
- Don’t automate the two-factor approval tap. It’s one line, and that line approves somebody else’s sign-in attempt too. Detection and delivery are automatic, the tap is a person.
- Don’t build a remote screen out of screenshot polling. I got 3.25 seconds per frame. Lowering the quality changed nothing. When capture and transfer are the bottleneck, back-end optimisation moves zero.
- Don’t assume screen recording works because screenshots do. On a sleeping screen, capture succeeds and recording dies instantly. Not knowing that, I spent my time suspecting a parser that was fine.
- Don’t assume Safari decodes it because Chrome did. Leave the resolution out of the decoder config and Chrome lets it slide while Safari refuses at the first keyframe.
- Don’t guard a stream that uses module-level global state with a single boolean flag. Every async section opens a check-then-use race. It needs something like a generation counter that enforces “only the newest call survives”.
- Don’t fire a periodic wake signal without reading state first. The screen flickered the whole time it fired every 20 seconds unconditionally, and it stopped once it only fired on a sleeping device.
- Don’t keep editing code while the symptom stays identical. I looked at a black screen and fixed four bugs, all four were real bugs, and not one of them caused the black screen. The simplest test should have come first. One screenshot would have closed it in five minutes.
- Don’t open one screen on two devices at once. The structure assumes a single viewer, so two attached devices push each other out through the generation counter and the picture resets forever. That’s the design working, and I have no plans to change it.
Honestly
- 3.25 seconds is a measurement left behind by the polling build. There’s no table of dozens of timed frames with a mean and a variance. It’s the number recorded as the reason for scrapping that build, and this post claims nothing more for it.
- I never timed the H.264 path in seconds. “Real time” means tapping and watching the reaction makes operation possible, not that I hold a millisecond figure. I didn’t measure end-to-end latency.
- Bitrate is configured at 2.5 Mbps and the actual output came in lower. I picked that value after watching a 3 Mbps setting produce around 1 Mbps. Why the encoder delivers under its setting, I don’t know. I didn’t dig.
- I still don’t know why the stream opens twice. I closed it off safely on the server side and never investigated the client. The generation counter is a defence, not a fix for the cause.
- The iPhone track never started. The iPhone route remained an unbuilt design; I confirmed none of it on a device.
- One device, one Android version. I confirmed the lock screen capture block on a device that carries an extra manufacturer security layer on top. Whether other manufacturers behave the same, I didn’t check.
- There’s a hidden assumption. This mirroring only works while the target phone sits on the same wireless network. Carrying the phone out broke wireless debugging and it wouldn’t reconnect. I have a guess at the cause and never confirmed it. The device stays docked in use anyway, so I stopped there.
- It cost no money. Extra spend: ₩0. The phone and the machine were already here, and not one line of this uses a paid API.
What I’d tell myself before starting
Before building, I saw this as “forwarding a notification”. After building, it was split three ways, and the split lines were drawn by what the OS hands over, not by my design.
Cheapest first: a notification I only read is one app. A notification I have to tap demanded a whole video pipeline and left four bugs behind. On the tested locked device and capture path, the result remained black.
The last one bought me the most expensive lesson. When the symptom stays the same, stop editing code and run the simplest test first. I did it in the opposite order. I’ve made this mistake in another shape already — a checker returned green and I believed the checker instead of looking at the thing itself. This time there was no checker, just me, fixing real bugs in front of a screen that never changed.
Updated October 6, 2026: added public diagnostics and sources, and scoped capture restrictions to the tested path. There is still no measured end-to-end latency for the H.264 path.
Editorial correction, November 4, 2026: Scoped the flag and lock-screen conclusions to the tested implementation. Original measurements are unchanged.