I Rebooted to Fix 129MiB Free. It Broke My AI Agent’s Login for Three Hours.
My home server ran out of disk. I fixed it, rebooted, and rebooted, and rebooted, and three hours later I realized my remote-access bridge was dead. That’s the thing that lets me run my AI coding agent from my phone. The routine daemon logs looked clean. I hadn’t yet inspected the CLI’s own retry events. It just wasn’t answering.
This is a post about that chain. A disk alarm, a wrong theory I nearly built a workaround around, and the actual bug: an AI agent breaking its own login because of a setting it wasn’t even using.
The math didn’t add up
Free space on my always-on Mac mini dropped to 129MiB, out of 228GiB total. That mini is the control tower for my self-hosted AI setup. I’d downloaded a game that said it needed 9GB. I’d lost more than 20GB. Those numbers don’t match, and I don’t like it when they don’t match.
I split the difference into two separate problems instead of guessing:
- 9.3GB was leftover game data that never got cleaned up (a 7.6GB pack file plus 1.7GB unpacked next to it).
- The rest was memory pressure quietly inflating the OS swap volume to 16.1GB, completely unrelated to the game.
Two causes, same symptom. If I’d only looked at the game folder, I’d have “fixed” it and watched the disk fill right back up.
Cleaning it up was the easy part
Clearing about 12.5GB of stale desktop-app cache and bundle data brought me from 129MiB to 14GiB, immediately. A reboot released the swap volume too. Free space went to 51GiB, swap dropped to 2.0GB. The follow-up recorded for the original post showed 49GiB free, with swap still at 2.0GiB. The 2GB gap from 51 to 49 is normal drift, not a regression.
| Point in time | Free space | Swap used |
|---|---|---|
| Alarm (before cleanup) | 129MiB | 16.1GB |
| After clearing app cache/bundles | 14GiB | 16.1GB |
| After reboot | 51GiB | 2.0GB |
| Follow-up recorded for the original post | 49GiB | 2.0GB |
Disk problem solved in under twenty minutes. I stepped away from the Mac mini feeling good about it. I shouldn’t have.
The reboot broke something, and hid it well
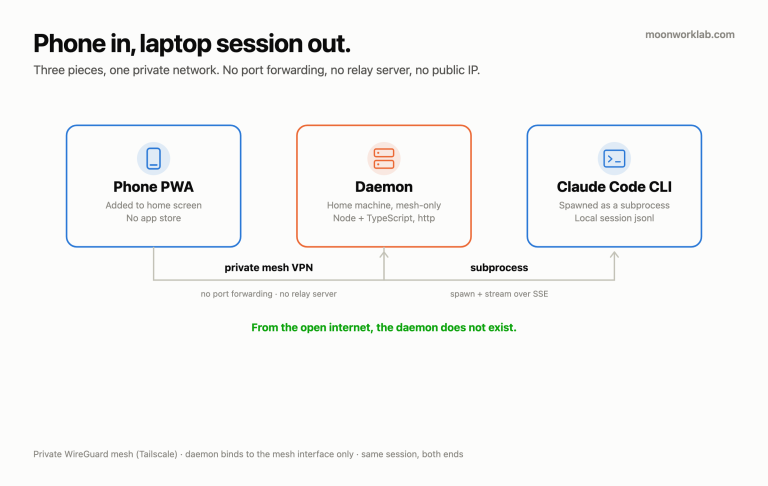
Rebooting the Mac mini restarts everything running on it. That includes the daemon for my remote-access bridge — a self-hosted setup that lets me open a web app on my phone and drive my AI coding agent from anywhere. After the reboot, that bridge just stopped answering.
I didn’t notice for about three hours. That’s the real cost of this incident. Not the disk. The blind spot right after fixing the disk.
Here’s what made it hard to catch: the routine daemon logs showed no crash or stack trace when I first looked. It looked idle, not broken. I’ve said this before and I’ll keep saying it — a clean log isn’t proof something’s healthy. It’s only proof nothing logged an error. Those aren’t the same thing.
The theory that almost sent me down the wrong hole
My first working theory: the daemon process had no controlling terminal, and some newer version of the CLI it calls just hangs without one before it initializes. It’s a plausible story. It’s true for some tools, genuinely, and it would’ve explained a silent hang well enough that I nearly wired in a pseudo-terminal library to fake one for the daemon.
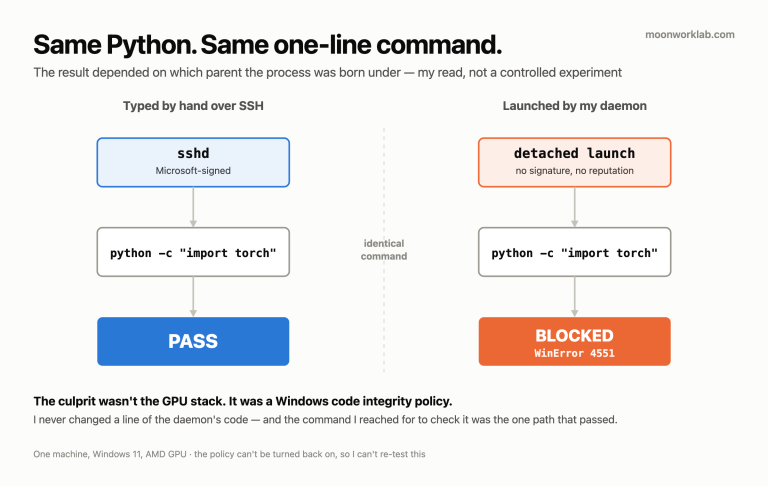
I didn’t, because something nagged at me. Every time I tested from inside my desktop app’s own session, the same command worked fine. If the TTY theory were right, that shouldn’t have been so consistent. Turned out the app’s own environment was quietly routing around the real problem a different way. My “successful” tests were passing for a reason that had nothing to do with what I was testing. I only killed the TTY theory by stripping everything down — no app context, a bare environment, nothing but the command itself — and watching it fail the exact same way with a terminal present. If a TTY were the fix, that run should’ve worked. It didn’t. Theory dead.
Don’t debug from inside the one context that might be masking the bug
This is the real antipattern here, and it isn’t specific to this bug. If the only place your fix seems to work is the same environment where the failure started, that’s not confirmation. That’s a warning sign. My desktop app’s session was never a clean test of the daemon’s behavior, because it wasn’t running the same way the daemon runs. I burned real time on that, before I reproduced the failure from zero instead of reasoning harder about a theory that already fit the symptoms a little too well.
What was actually happening
I traced the failure to a user-level endpoint override written by the desktop app. The background service read that same setting without the desktop app’s host-authentication context. In my isolation tests, leaving the override present led to connection or authentication retries; excluding that settings source let the subscription login path work again. That was the result on this setup. I didn’t establish how every current CLI version or every custom endpoint behaves.
Nobody changed a value here. A setting for a feature I don’t use was enough to break a login path for a completely different process, just by existing in a file two unrelated things both happened to read.
The fix wasn’t to touch the setting
I didn’t patch the value, and I didn’t turn the experimental feature off. I changed how the daemon launches its CLI process, so it explicitly only reads project- and local-level config, never the shared user-level file the desktop app writes to. The desktop app can keep writing that setting forever, for whatever feature it wants. The daemon simply never sees it. That removes this user-settings path from the daemon’s launch. It doesn’t remove inherited environment variables or replace a real health check.
The diagnostic I can actually share
This happened on September 28, 2026, with Claude Code 2.1.x on macOS. I didn’t retain the exact patch version in the incident record. The process was started by a launchd service, outside the desktop app’s own authentication context.
The setting was env.ANTHROPIC_BASE_URL in ~/.claude/settings.json. It pointed at a local proxy managed by the desktop app. Targeted CLI diagnostics showed api_retry, error:unknown, status:null, and ConnectionRefused. Those details weren’t visible in the routine daemon log I first checked.
| What I observed | What I checked next |
|---|---|
| The desktop session worked; the background service didn’t | Working directory, inherited environment, and settings sources |
| Routine logs looked quiet | Whether the CLI reached a final result or kept retrying |
| A user-level endpoint override was present | The same small request with that settings source excluded |
These are the public command names behind that comparison:
claude --version
claude --help
env -u ANTHROPIC_BASE_URL claude --setting-sources project,local -p "Reply OK only."
The last command is a minimal form of the isolation test, not a fresh retest of the old failure. It assumes an already authenticated subscription and uses that subscription’s quota. I ran the comparison outside the desktop app context, from the intended project directory. If the command stalls, stop it and inspect the diagnostic output; a process that stays alive hasn’t proved that login works.
--setting-sources project,local excludes user-level settings, including user hooks and permissions. It doesn’t erase an environment variable inherited from a parent process; that’s why the example also unsets the named variable for this command. Check which settings your service actually needs before adopting it. An intentional custom endpoint needs its own reachability and credential checks. Removing it would change the setup you’re trying to test. Managed organizational policy is a separate layer.
The official references are Claude Code settings and the CLI flag reference. My phone-access bridge article explains the service this affected; the project-memory article explains why settings and project context matter.
One good thing came out of the whole afternoon. I ended up writing a small health-check script that pings about 15 of my self-hosted services, and draws a status map of how they’re wired together around the Mac mini. Wasn’t the goal. Still useful.
Closing
Letting an AI agent run your own infrastructure can expose failures in its own execution environment, as this incident did. Not through malice, not through a bad decision — just a leftover setting nobody was watching. The lesson isn’t “audit every config file.” It’s narrower than that, and more useful: when something looks broken but nothing is logging an error, don’t settle for the first theory that fits. Reproduce it from zero, outside whatever context might be quietly covering for it. That’s the only way I actually found this one.
Updated October 6, 2026: added the product and setting names, a public diagnostic, and source links. The exact historical CLI patch version is unavailable; disk figures remain the original incident data.
Editorial correction, November 4, 2026: Removed an inevitable-failure generalization. Original measurements are unchanged.