One More Offloaded Layer Coincided With a 29% Throughput Drop.
Moving an idle occupier from one GPU layer to two coincided with a 29% generation-speed drop. The 70MB counter delta does not establish the cause.
Moving an idle occupier from one GPU layer to two coincided with a 29% generation-speed drop. The 70MB counter delta does not establish the cause.
At depth 7,168, compressed cache reached 5.27 tok/s versus 9.31 for fp16 in the same fork. A later run exited with 0xC0000409; the crash cause is unconfirmed.
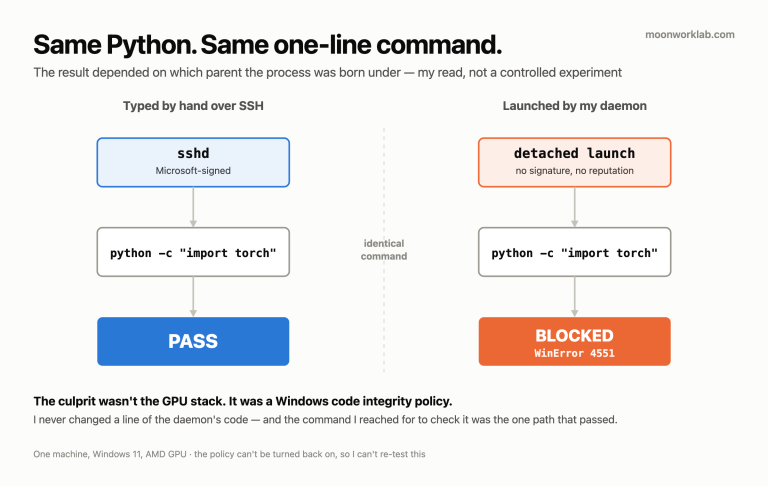
Manual SSH import passed while a WMI launch failed with WinError 4551. Disabling a policy restored that setup; the exact launch-path mechanism was not isolated.
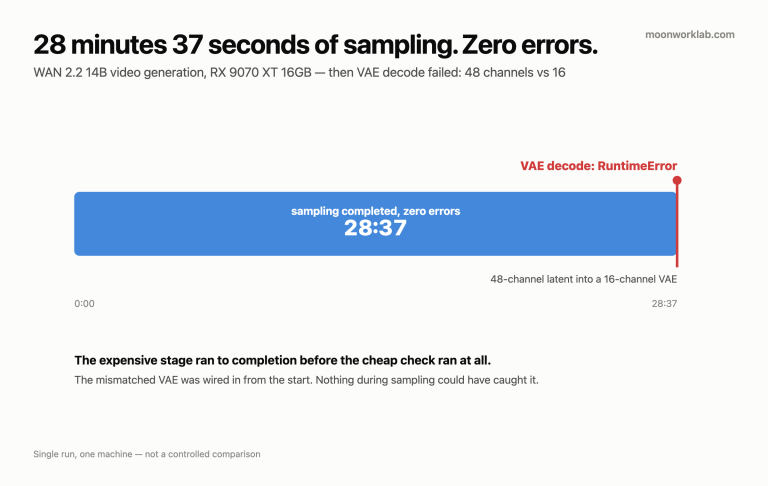
A mismatched VAE ended a WAN 2.2 run after 28 minutes of sampling. The successful retry used different settings, so its timing is not a controlled comparison.
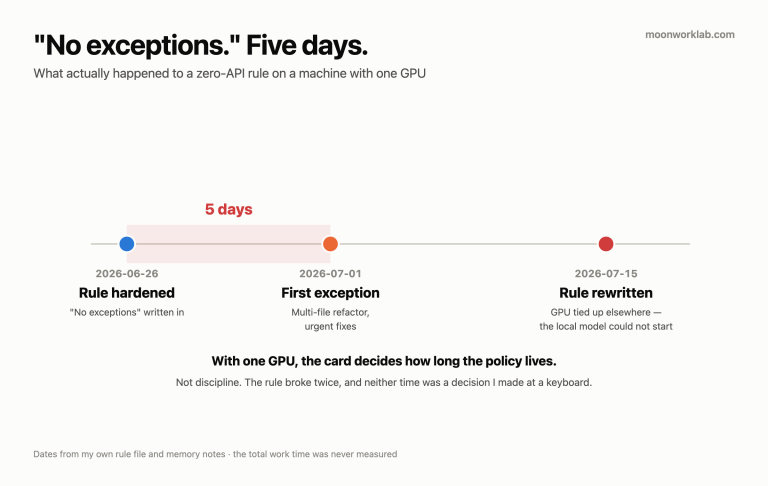
My first exception concerned multi-file refactors. GPU contention complicated the local-coding policy later. The chronology matters when explaining why the rule changed.
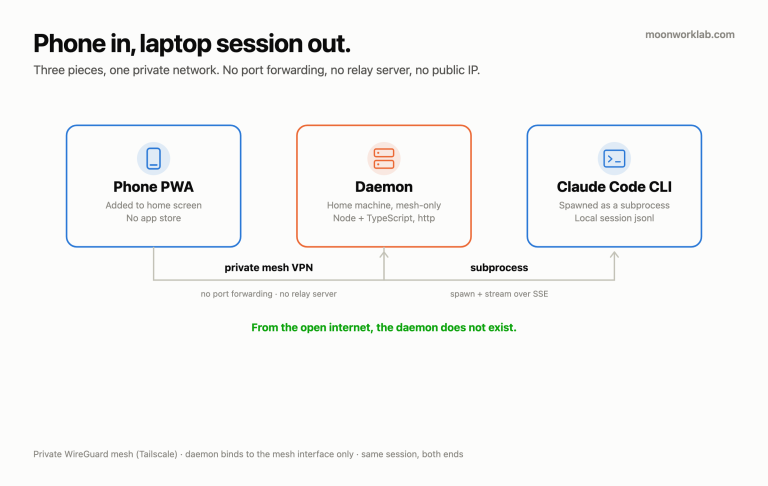
I built an AI-assisted phone bridge around existing CLI sessions. A restart loop, argument parsing, keyboard handling, and stale PWA state exposed different boundaries.
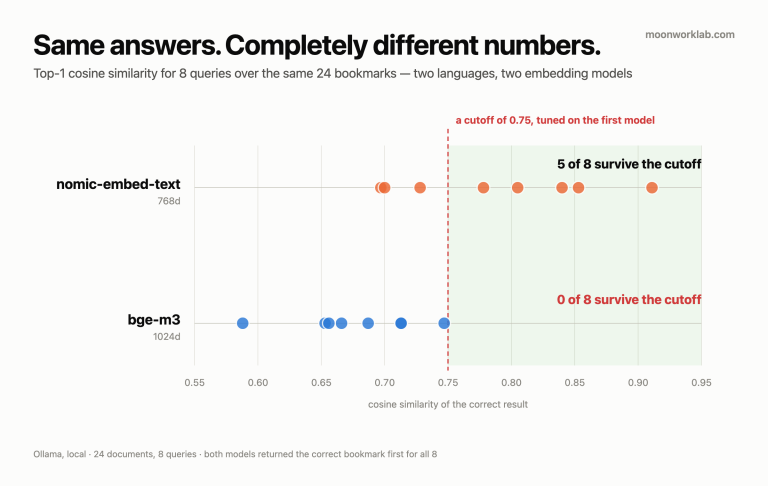
Two local embedding models ranked the same 24 bookmarks identically — 8 of 8 correct each. Their similarity scores sat in almost non-overlapping ranges, and one hardcoded 0.75 cutoff silently erased every result from one of them.
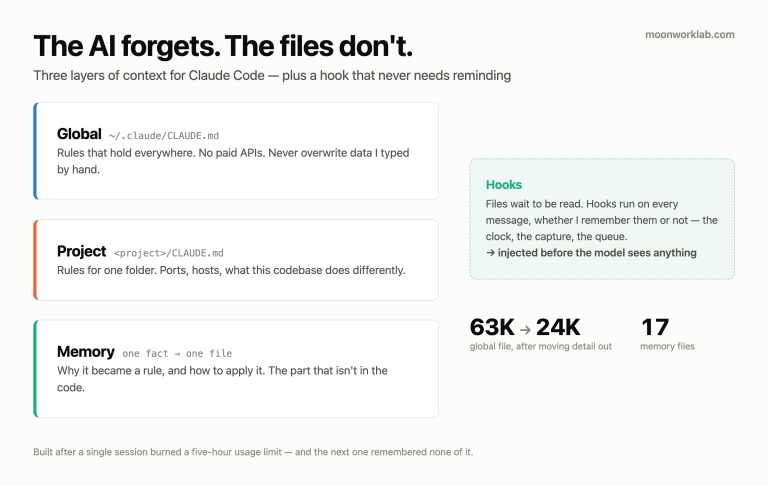
A cloud model wrote 1,900 lines in one session and burned my five-hour limit — then the next session remembered none of it. Three layers of context files plus hooks, and what each one is actually for.