I Tuned CPU Expert Offload on Two GPUs. One Slowed Down Without Crashing.
I swept expert CPU offload on two PCs. The tables show throughput and a silent speed cliff; they do not isolate the driver’s memory policy.
Benchmarks and real-world performance of language models running on ordinary consumer hardware.
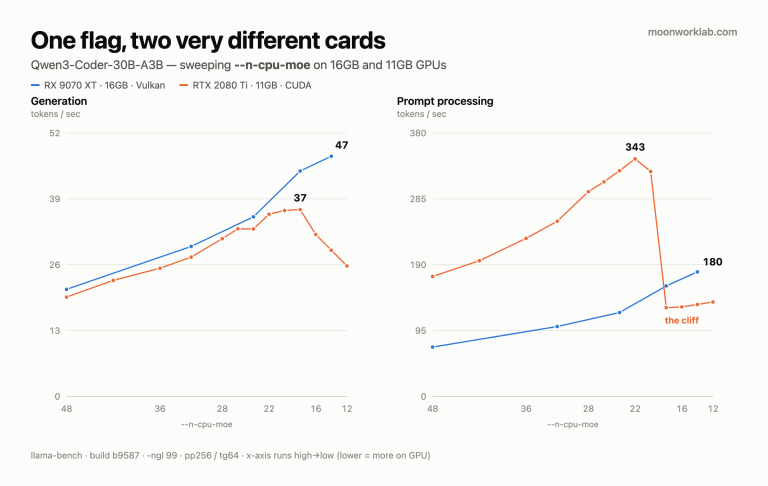
I swept expert CPU offload on two PCs. The tables show throughput and a silent speed cliff; they do not isolate the driver’s memory policy.
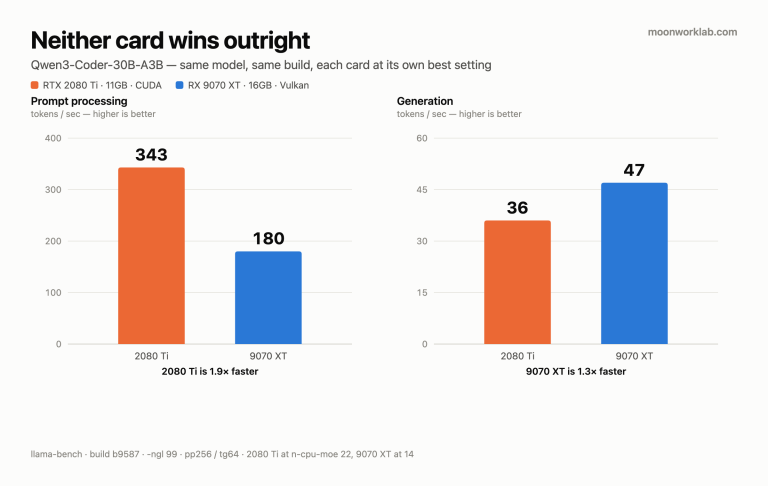
Same model, same build, same test — one on an RTX 2080 Ti (11GB, CUDA), one on an RX 9070 XT (16GB, Vulkan). The result split: 1.9x prompt processing one way, 1.3x generation the other.
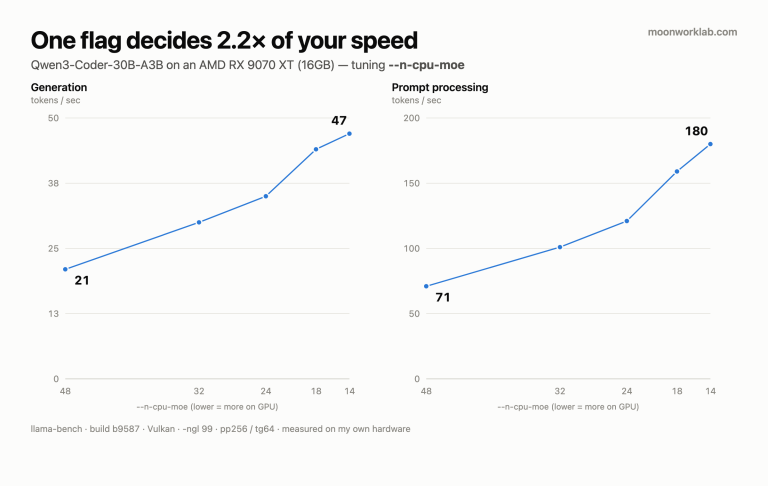
Real llama-bench numbers for Qwen3-Coder-30B-A3B on an AMD RX 9070 XT (16GB, RDNA4) using llama.cpp with Vulkan — including the full n-cpu-moe sweep that took generation from 21 to 47 tok/s.