Both Embedding Models Were Right. Only One Survived My Threshold.
I sat down to confirm something I remembered. Months ago, when I added local semantic search to a bookmark extension, I was sure one embedding model had fallen apart on my non-English bookmarks. I swapped models, it got better, I moved on.
So I rebuilt the test to write it up. It didn’t reproduce. Both models handled everything I threw at them, in both languages, without a single miss. That cost me an evening of measurements and the post I had already outlined, which I threw away.
What I found instead is worse, because it doesn’t announce itself at all.
The setup
24 bookmark-style titles, split across two languages. 8 queries, also split across both. Two embedding models running locally through Ollama:
nomic-embed-text— 768 dimensions, about 300MBbge-m3— 1024 dimensions, about 1.2GB
For each query I embedded everything, took cosine similarity against all 24 documents, and looked at what came first.
Result 1: both models were right, every time
8 out of 8 for both. Every query returned the correct bookmark in first place, including the non-English ones on the smaller English-oriented model.
So my memory was wrong, and I’ll take that trade — I would much rather find out here than after publishing it as a finding somebody else acts on.
Result 2: the numbers live in different worlds
Then I looked at the actual similarity values.
nomic-embed-text |
bge-m3 |
|
|---|---|---|
| Correct result ranked first | 8 / 8 | 8 / 8 |
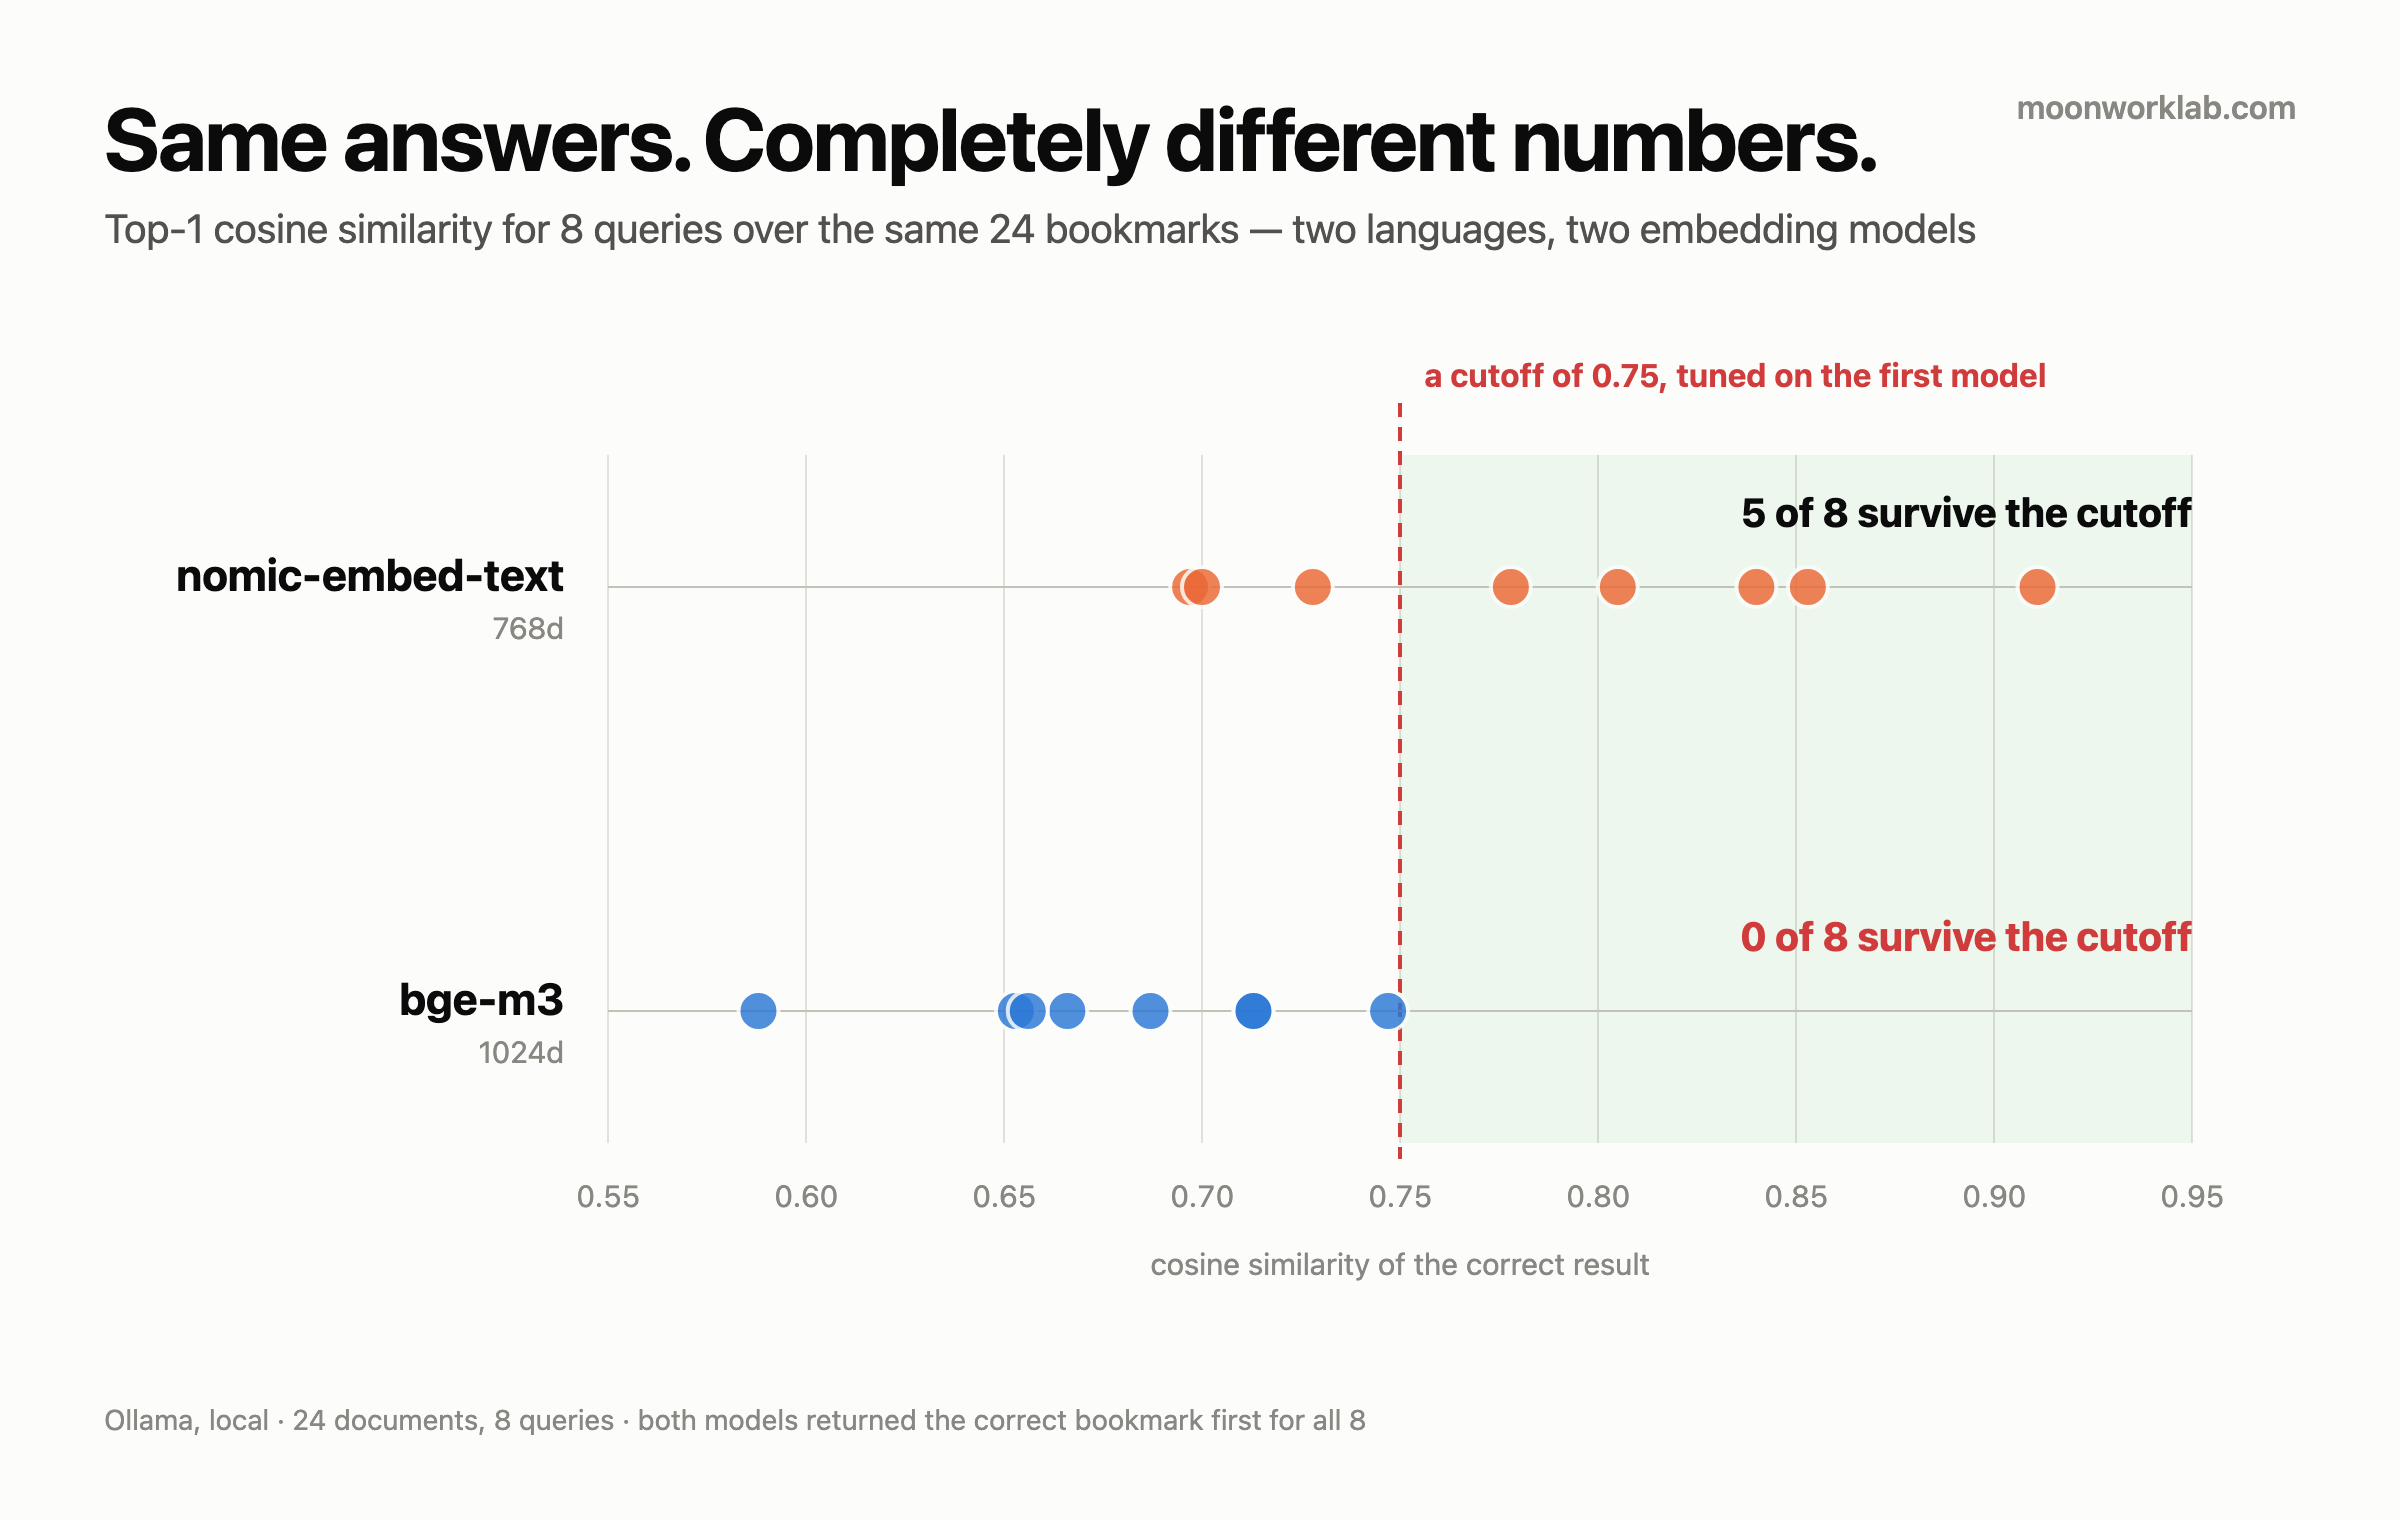
| Similarity of that result | 0.697 – 0.911 | 0.588 – 0.747 |
| Highest score seen | 0.911 | 0.747 |
The ranges overlap: 0.6972–0.7474 sits inside both. The highest bge-m3 score is above the lowest nomic score. What matters for this example is narrower: every bge-m3 top result falls below my 0.75 cutoff.
Both models put a relevant result first for all eight queries. I didn’t establish that the complete 24-document ranking was identical.
The trap
Here’s the line of code that gets written in every semantic search project:
if (similarity > 0.75) showResult(doc)It’s an easy thing to write. At 0.75, five of my eight queries clear the cutoff. That doesn’t validate the number for production: this small fixture has no negative queries to show which irrelevant results it would admit.
Now swap the model. Same code, same threshold, same bookmarks.
0 of 8. Every single correct answer falls below the cutoff and gets filtered out.
The search doesn’t error. The model loads fine. The ranking is still perfect. The results are just gone — the user types a query and sees an empty list, and nothing anywhere says why.
This is the same shape as a problem I hit tuning GPU memory offload: no crash, no warning, just quietly wrong. Those are the expensive ones.
What I do instead
For this small bookmark picker, I show the top N candidates and let the user choose. That avoids losing every row to one uncalibrated cutoff. Top N doesn’t prove relevance, though: a query with no good match still has a highest-scoring document. A system that must reject bad matches needs its own validation set and a threshold calibrated for that model and corpus.
Where I do combine scores, I normalise first:
final = 0.65 × semantic + 0.35 × fuzzy // each min-max normalisedMin-max normalisation rescales whatever the model handed me into 0–1 within the current result set. The absolute scale stops mattering, which is exactly what I want.
The fuzzy half serves a different purpose in my bookmark picker: preserving literal title matches alongside semantic candidates. When I type a word from a title, I want that evidence represented in the ranking.
Don’t do these
- Don’t carry a cutoff into a new model without validating it. A fixed threshold can be useful, but the number needs evidence from the task it will serve.
- Don’t compare similarity scores across models. 0.70 from one is not 0.70 from another. Their numeric scales aren’t calibrated to one another.
- Don’t assume a model swap is a drop-in. Dimensions change, so your cached vectors are invalid, and the scale changes, so your tuning is invalid.
- Don’t trust your memory of a bug. I nearly published a confident claim that my own test then contradicted.
Honest limits
- This is a small test. 24 documents, 8 queries, short titles. A bigger corpus or longer text could behave differently.
- Two models only. I didn’t test any of the dozens of other embedding models out there.
- Neither model is bad here. Both got every answer right. The problem is the number attached to the answer, not the answer.
- I still don’t know what I actually saw months ago. Model versions move, and I didn’t keep the data. That’s on me.
Download the test fixture and results
- Original Python test — save it as
embed_test.py. - Per-query top scores.
- Archived similarity arrays.
The script contains all 24 synthetic titles and eight English/Korean queries. These aren’t private browser bookmarks. It uses Python’s standard library and sent plain text without model-specific prefixes in the historical test.
With local Ollama and both models already installed, run python3 embed_test.py in an empty working folder. It writes embed_result.json in that folder, so keep the archived result separately.
This archived script uses Ollama’s older /api/embeddings endpoint. The current API reference describes /api/embed, a different endpoint. I didn’t retain the old model digests or Ollama version, so current model tags can produce different numbers. This fixture demonstrates cutoff sensitivity; it isn’t a comparison of each model’s best possible retrieval quality.
The thing this came out of
All of this lives in MarkJump, a Chrome extension I built for searching bookmarks. Fuzzy search is the default and works offline with no setup. The semantic search above is optional and off unless you turn it on, and when you do, it only talks to a local Ollama endpoint — localhost, enforced by the host permission itself. No accounts, no telemetry, no cloud.
It’s free, and I’d be glad if you gave it a try: MarkJump on the Chrome Web Store.
Closing
I went looking for a model that was broken, and what I found instead was a number that meant nothing on its own. Both models answered every question correctly. A single hardcoded constant was ready to throw all of it away.
Correction, October 6, 2026: The inequality was backwards in the original text. The correct statement is that 0.747 (bge-m3) is greater than 0.697 (nomic), not the other way around. No original measurements were changed, only the inequality in the text. I also added the archived fixture and results for readers to inspect.