Skip to content
MoonWorkLab
  • Local LLM & GPU
  • AI-Assisted Dev
  • Hardware & Desktop
  • Self-Hosting
  • About
  • Contact
MoonWorkLab
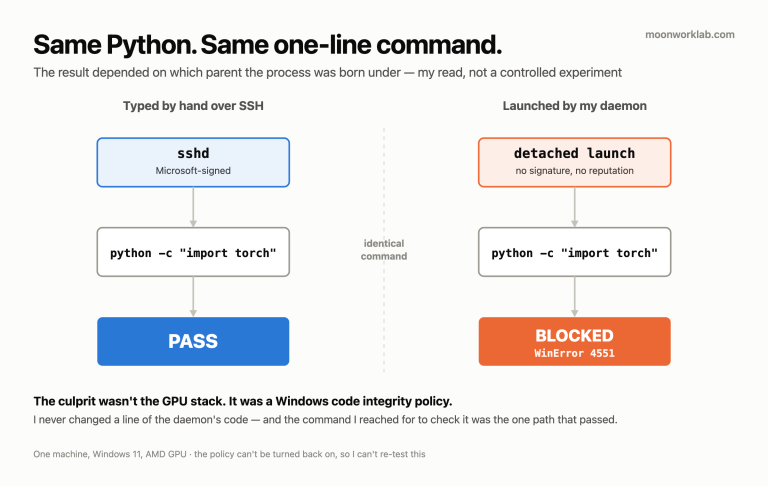
  • Same Python, Same Command — One Launch Path Passed, the Other Hit WinError 4551
    Self-Hosting & Infrastructure

    Same Python, Same Command — One Launch Path Passed, the Other Hit WinError 4551

    ByMoonWork August 17, 2026

    Same machine, same Python, same one-line command. The result depended on who launched that Python. When I opened an SSH session by hand and typed python -c “import torch”, it passed. When my daemon brought the GPU image server up on that machine automatically, the same import torch died like this: OSError: [WinError 4551] ……
    Read More Same Python, Same Command — One Launch Path Passed, the Other Hit WinError 4551Continue

  • My Local Model Wrote the Code for Free. Orchestrating It Cost $0.66 a Unit.
    AI-Assisted Development

    My Local Model Wrote the Code for Free. Orchestrating It Cost $0.66 a Unit.

    ByMoonWork August 17, 2026August 18, 2026

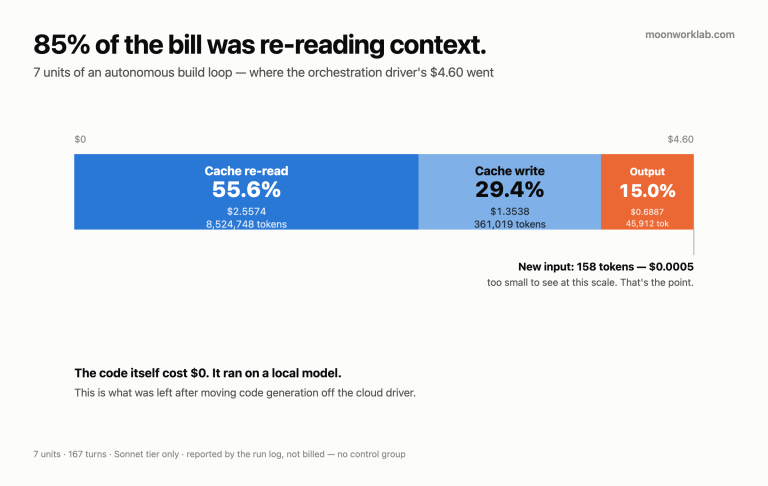
    I built a loop that puts up a personal homepage on its own. It’s a static site, résumé-shaped, and I cut the work into units. Every unit spawns a fresh cloud agent. That agent plans, and it doesn’t write the code itself. It hands the code off to a local model on a remote machine….

    Read More My Local Model Wrote the Code for Free. Orchestrating It Cost $0.66 a Unit.Continue

  • WAN 2.2 Sampled for 28 Minutes, Then Died at VAE Decode — 48 Channels vs 16
    Local LLM & GPU

    WAN 2.2 Sampled for 28 Minutes, Then Died at VAE Decode — 48 Channels vs 16

    ByMoonWork August 17, 2026

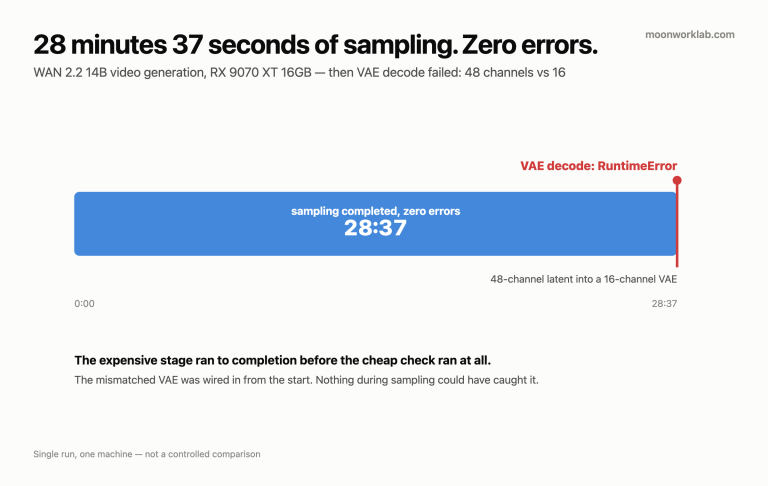
    My GPU worked for 28 minutes and 37 seconds without a single complaint. Every step ran, and sampling finished. Then the last node in the graph printed this. RuntimeError: expected input to have 48 channels, but got 16 Decoding never started. Everything those 28 minutes and 37 seconds produced went straight in the bin. The…

    Read More WAN 2.2 Sampled for 28 Minutes, Then Died at VAE Decode — 48 Channels vs 16Continue

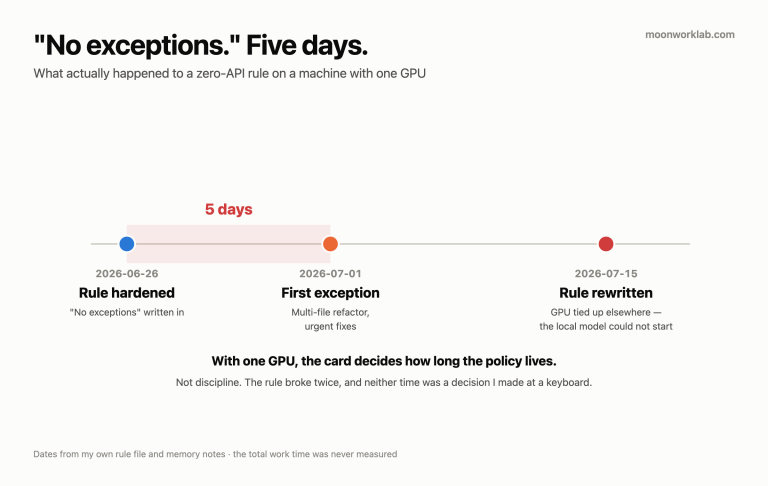
  • Timeline: rule hardened to no exceptions on 2026-06-26, first exception conceded 2026-07-01 five days later, rule rewritten 2026-07-15 after the GPU was tied up
    AI-Assisted Development

    I Wrote “No Exceptions” Into My Coding Rule. One GPU Broke It in Five Days.

    ByMoonWork August 16, 2026August 19, 2026

    My development rules contain one line: Code generation goes to the local model. The cloud model plans and reviews. On 26 June 2026 I added two words to it: no exceptions. That phrase survived five days. On 1 July I conceded the first exception and rewrote the line myself. The rule itself came out of…

    Read More I Wrote “No Exceptions” Into My Coding Rule. One GPU Broke It in Five Days.Continue

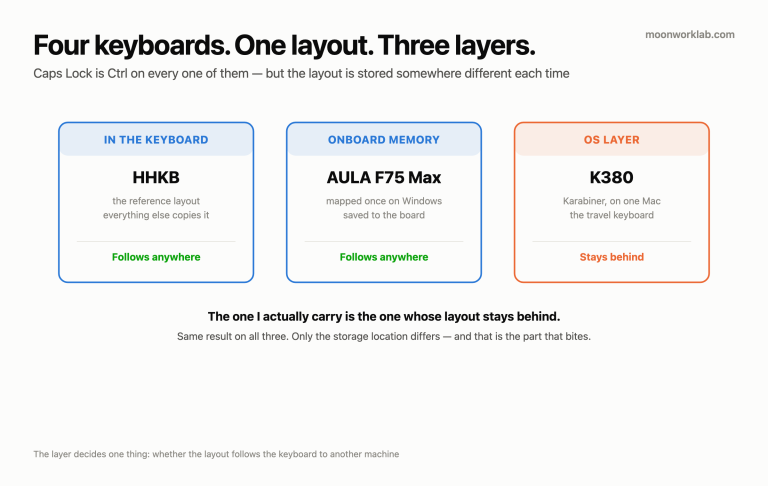
  • Three cards showing where each keyboard stores its layout: HHKB in the keyboard, AULA in onboard memory, K380 in the OS layer, with only the OS one failing to follow to another machine
    Hardware & Desktop

    I Own Four Keyboards and One Layout — and One Thing I Couldn’t Unify

    ByMoonWork August 16, 2026

    I own four keyboards. Different switches, different sizes, bought years apart. They all run one layout. Every one of them is set up the way my HHKB is set up: the Caps Lock position produces Ctrl or Command, and everything else matches as far as each board allows. The HHKB is the reference, and the…

    Read More I Own Four Keyboards and One Layout — and One Thing I Couldn’t UnifyContinue

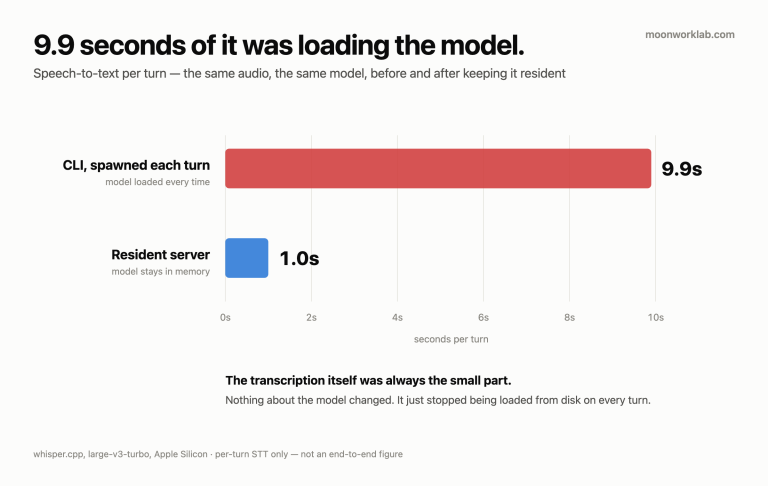
  • Bar chart: speech-to-text per turn drops from 9.9 seconds when the CLI is spawned each turn to 1.0 second with a resident server
    Local LLM & GPU

    My Voice Assistant Spent 9.9 Seconds Loading Whisper. Every Single Turn.

    ByMoonWork August 16, 2026

    I built a thing that answers when I talk to it. It takes the microphone, turns what I said into text, hands that to a model, and speaks the reply back out loud. I never touched a cloud speech API. The brain in the middle is a different story, and I deal with it head…

    Read More My Voice Assistant Spent 9.9 Seconds Loading Whisper. Every Single Turn.Continue

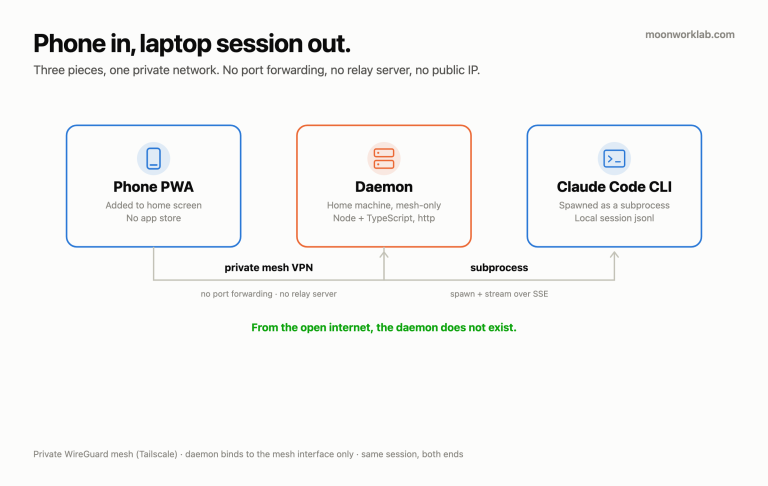
  • Architecture diagram: phone PWA connects over a private mesh VPN to a daemon on a home machine, which spawns Claude Code CLI as a subprocess. No port forwarding, no relay server.
    Self-Hosting & Infrastructure

    I Drive Claude Code From My Phone. One Night It Restarted Its Own Daemon 105 Times.

    ByMoonWork August 15, 2026

    My coding sessions run on a machine at home, and I’m away from that machine far more than I’m sitting in front of it. So I built a way to keep typing into those same sessions from my phone. Moonlight does this for game screens. I did it for text. The most expensive thing that…

    Read More I Drive Claude Code From My Phone. One Night It Restarted Its Own Daemon 105 Times.Continue

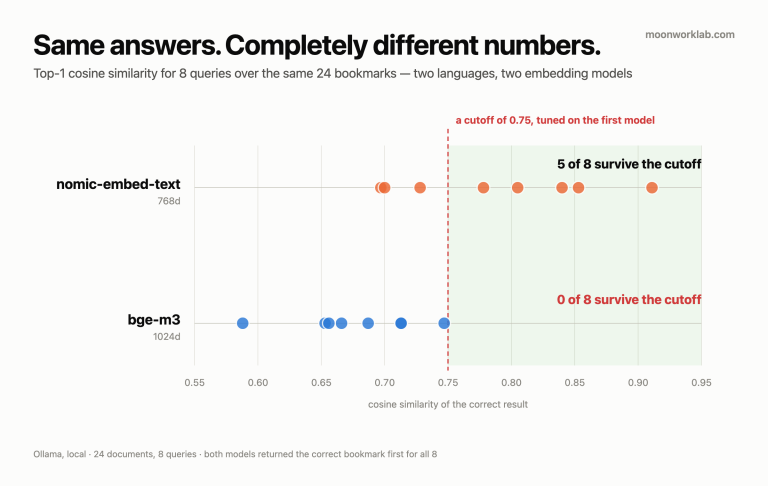
  • Dot plot of top-1 cosine similarity for two embedding models with a 0.75 cutoff line
    Local LLM & GPU

    Both Embedding Models Were Right. Only One Survived My Threshold.

    ByMoonWork August 15, 2026

    Two local embedding models ranked the same 24 bookmarks identically — 8 of 8 correct each. Their similarity scores sat in almost non-overlapping ranges, and one hardcoded 0.75 cutoff silently erased every result from one of them.

    Read More Both Embedding Models Were Right. Only One Survived My Threshold.Continue

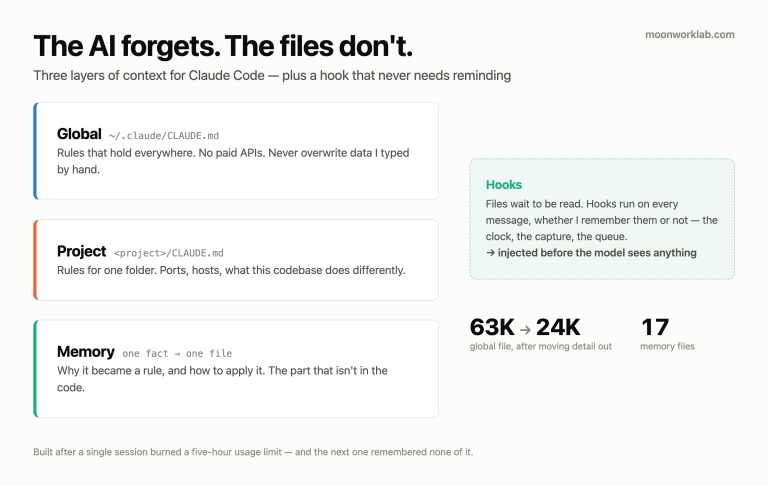
  • Diagram of three context layers — global CLAUDE.md, project CLAUDE.md, and one-fact-per-file memory — plus hooks injected on every message
    AI-Assisted Development

    I Burned Five Hours of AI Budget in One Session. Here’s the System I Built Next.

    ByMoonWork August 15, 2026

    A cloud model wrote 1,900 lines in one session and burned my five-hour limit — then the next session remembered none of it. Three layers of context files plus hooks, and what each one is actually for.

    Read More I Burned Five Hours of AI Budget in One Session. Here’s the System I Built Next.Continue

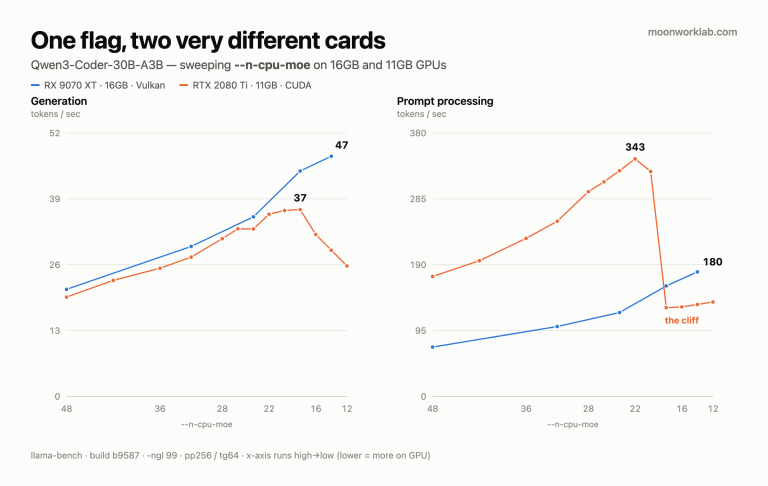
  • Two line charts comparing generation and prompt processing across n-cpu-moe values for an RX 9070 XT and an RTX 2080 Ti
    Local LLM & GPU

    The One llama.cpp Flag That Decides Your Speed: Tuning –n-cpu-moe

    ByMoonWork August 15, 2026August 15, 2026

    Fitting a 30B MoE model into 16GB of VRAM comes down to one flag. Full n-cpu-moe sweeps on a 16GB and an 11GB card — including the silent VRAM overflow that costs 2.5x with no error.

    Read More The One llama.cpp Flag That Decides Your Speed: Tuning –n-cpu-moeContinue

Page navigation

Previous PagePrevious 1 2 3 Next PageNext

© 2026 MoonWork Lab — every number measured on hardware I own.
About · Contact · Privacy · Affiliate Disclosure

  • Local LLM & GPU
  • AI-Assisted Dev
  • Hardware & Desktop
  • Self-Hosting
  • About
  • Contact