Skip to content
MoonWorkLab
  • Local LLM & GPU
  • AI-Assisted Dev
  • Hardware & Desktop
  • Self-Hosting
  • About
  • Contact
MoonWorkLab
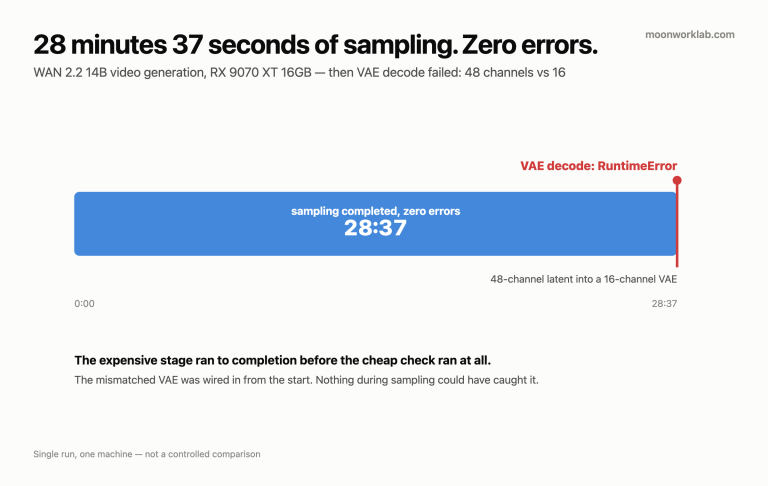
  • WAN 2.2 Sampled for 28 Minutes, Then Died at VAE Decode — 48 Channels vs 16
    Local LLM & GPU

    WAN 2.2 Sampled for 28 Minutes, Then Died at VAE Decode — 48 Channels vs 16

    ByMoonWork August 17, 2026November 4, 2026

    A mismatched VAE ended a WAN 2.2 run after 28 minutes of sampling. The successful retry used different settings, so its timing is not a controlled comparison.
    Read More WAN 2.2 Sampled for 28 Minutes, Then Died at VAE Decode — 48 Channels vs 16Continue

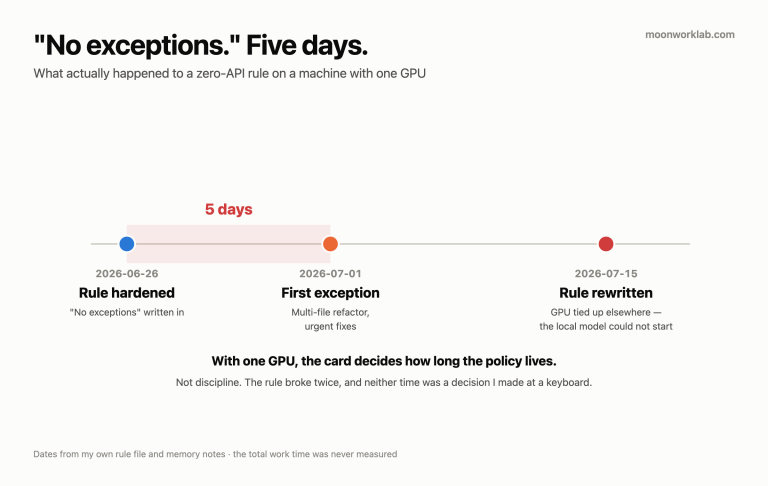
  • Timeline: rule hardened to no exceptions on 2026-06-26, first exception conceded 2026-07-01 five days later, rule rewritten 2026-07-15 after the GPU was tied up
    AI-Assisted Development

    My No-Exceptions Coding Rule Lasted Five Days. GPU Contention Came Later.

    ByMoonWork August 16, 2026November 4, 2026

    My first exception concerned multi-file refactors. GPU contention complicated the local-coding policy later. The chronology matters when explaining why the rule changed.
    Read More My No-Exceptions Coding Rule Lasted Five Days. GPU Contention Came Later.Continue

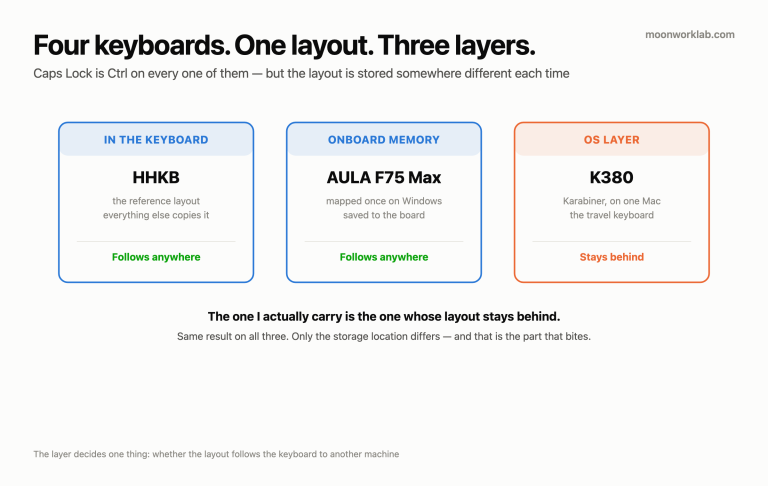
  • Three cards showing where each keyboard stores its layout: HHKB in the keyboard, AULA in onboard memory, K380 in the OS layer, with only the OS one failing to follow to another machine
    Hardware & Desktop

    I Own Four Keyboards and One Layout — and One Thing I Couldn’t Unify

    ByMoonWork August 16, 2026November 4, 2026

    Four keyboards, one preferred layout, and different places to store mappings. My K380 switching preference did not carry to every board; Air60 HE is wired-only.
    Read More I Own Four Keyboards and One Layout — and One Thing I Couldn’t UnifyContinue

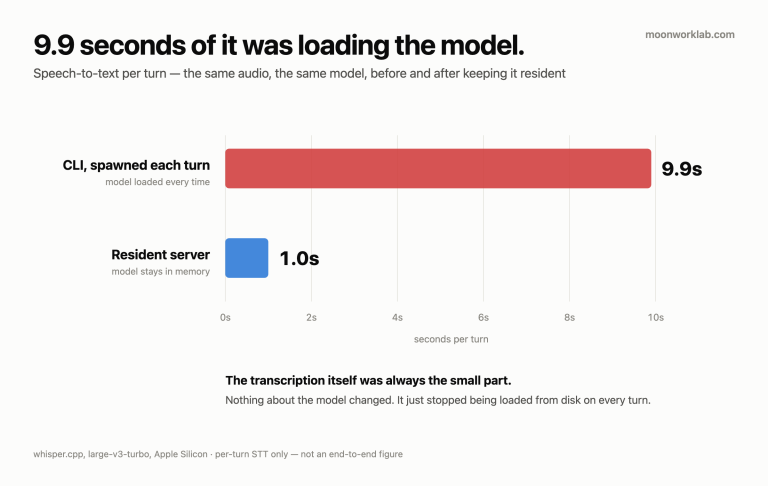
  • Bar chart: speech-to-text per turn drops from 9.9 seconds when the CLI is spawned each turn to 1.0 second with a resident server
    Local LLM & GPU

    My Voice Assistant Spent 9.9 Seconds Loading Whisper. Every Single Turn.

    ByMoonWork August 16, 2026November 4, 2026

    A resident whisper server reduced the recorded STT stage from about 9.9 to 1.0 seconds. End-to-end latency and answer-quality tradeoffs were not measured.
    Read More My Voice Assistant Spent 9.9 Seconds Loading Whisper. Every Single Turn.Continue

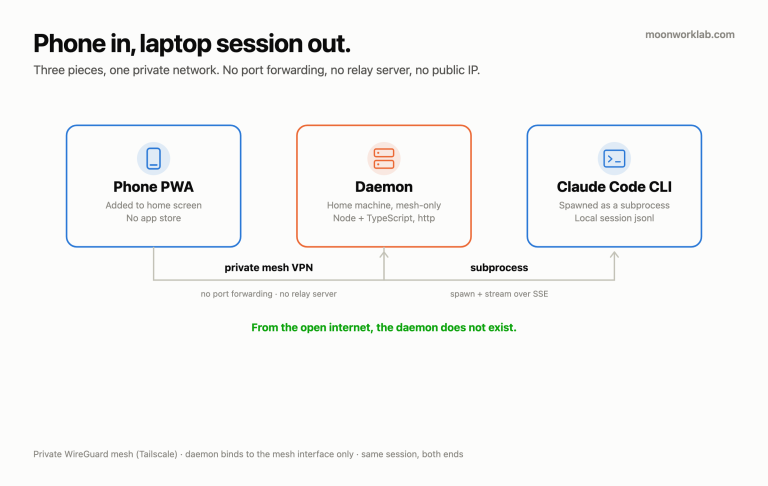
  • Architecture diagram: phone PWA connects over a private mesh VPN to a daemon on a home machine, which spawns Claude Code CLI as a subprocess. No port forwarding, no relay server.
    Self-Hosting & Infrastructure

    I Drive Claude Code From My Phone. One Night It Restarted Its Own Daemon 105 Times.

    ByMoonWork August 15, 2026November 4, 2026

    I built an AI-assisted phone bridge around existing CLI sessions. A restart loop, argument parsing, keyboard handling, and stale PWA state exposed different boundaries.
    Read More I Drive Claude Code From My Phone. One Night It Restarted Its Own Daemon 105 Times.Continue

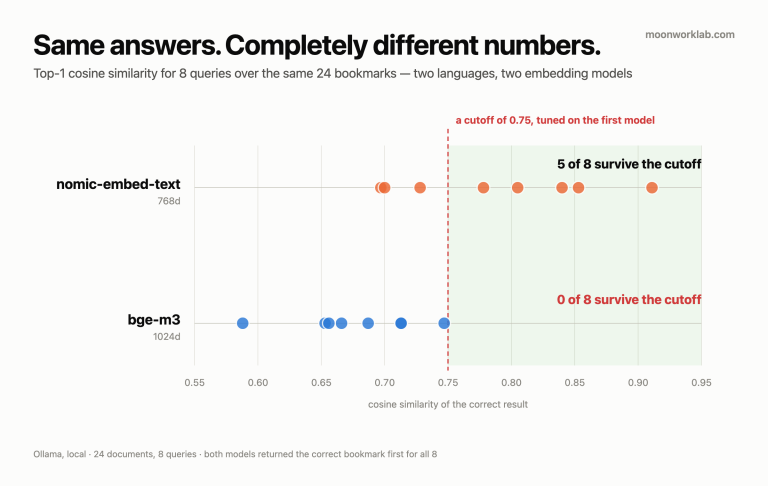
  • Dot plot of top-1 cosine similarity for two embedding models with a 0.75 cutoff line
    Local LLM & GPU

    Both Embedding Models Were Right. Only One Survived My Threshold.

    ByMoonWork August 15, 2026October 6, 2026

    Two local embedding models ranked the same 24 bookmarks identically — 8 of 8 correct each. Their similarity scores sat in almost non-overlapping ranges, and one hardcoded 0.75 cutoff silently erased every result from one of them.
    Read More Both Embedding Models Were Right. Only One Survived My Threshold.Continue

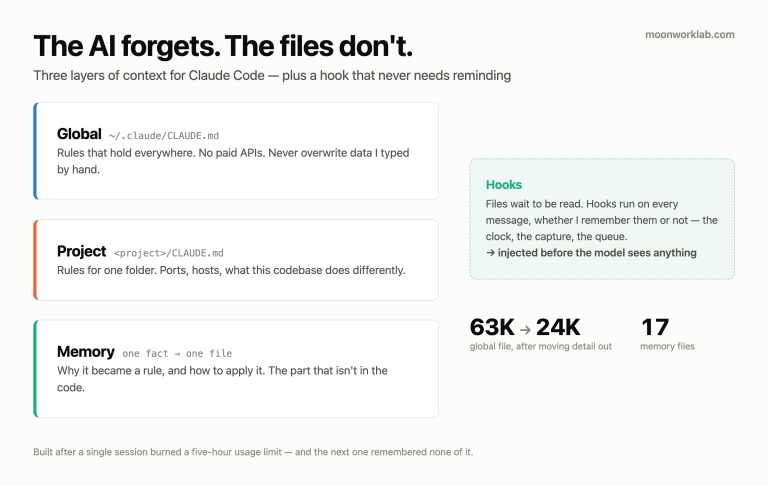
  • Diagram of three context layers — global CLAUDE.md, project CLAUDE.md, and one-fact-per-file memory — plus hooks injected on every message
    AI-Assisted Development

    I Burned Five Hours of AI Budget in One Session. Here’s the System I Built Next.

    ByMoonWork August 15, 2026November 4, 2026

    A cloud model wrote 1,900 lines in one session and burned my five-hour limit — then the next session remembered none of it. Three layers of context files plus hooks, and what each one is actually for.
    Read More I Burned Five Hours of AI Budget in One Session. Here’s the System I Built Next.Continue

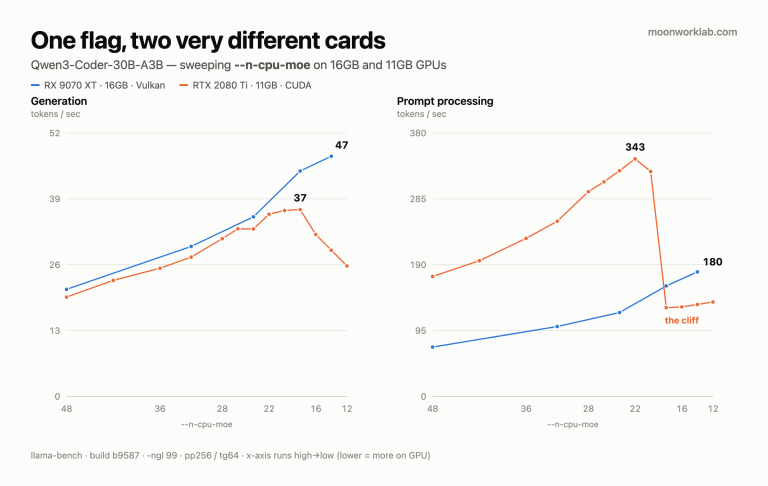
  • Two line charts comparing generation and prompt processing across n-cpu-moe values for an RX 9070 XT and an RTX 2080 Ti
    Local LLM & GPU

    I Tuned CPU Expert Offload on Two GPUs. One Slowed Down Without Crashing.

    ByMoonWork August 15, 2026November 4, 2026

    I swept expert CPU offload on two PCs. The tables show throughput and a silent speed cliff; they do not isolate the driver’s memory policy.
    Read More I Tuned CPU Expert Offload on Two GPUs. One Slowed Down Without Crashing.Continue

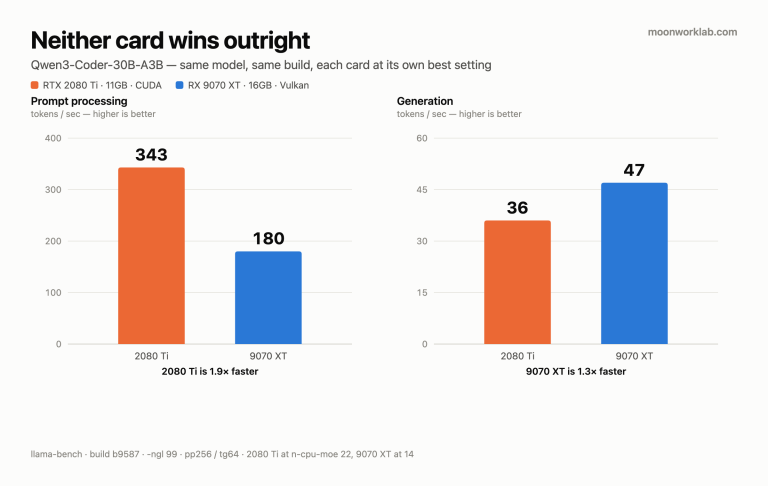
  • Bar charts: prompt processing 343 vs 180 tokens per second favouring the 2080 Ti, generation 36 vs 47 favouring the 9070 XT
    Local LLM & GPU

    Does CUDA Beat VRAM? I Ran the Same 30B Model on a 2080 Ti and an RX 9070 XT

    ByMoonWork August 14, 2026November 4, 2026

    Same model, same build, same test — one on an RTX 2080 Ti (11GB, CUDA), one on an RX 9070 XT (16GB, Vulkan). The result split: 1.9x prompt processing one way, 1.3x generation the other.
    Read More Does CUDA Beat VRAM? I Ran the Same 30B Model on a 2080 Ti and an RX 9070 XTContinue

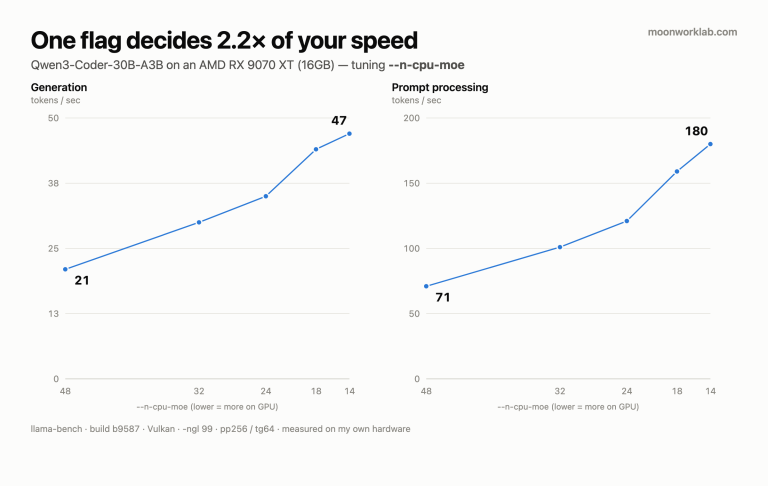
  • Line charts: generation rises 21 to 47 tokens per second and prompt processing 71 to 180 as n-cpu-moe drops from 48 to 14
    Local LLM & GPU

    I Ran Qwen3-Coder 30B on an AMD RX 9070 XT — 47 tok/s, No ROCm Required

    ByMoonWork August 13, 2026November 4, 2026

    Real llama-bench numbers for Qwen3-Coder-30B-A3B on an AMD RX 9070 XT (16GB, RDNA4) using llama.cpp with Vulkan — including the full n-cpu-moe sweep that took generation from 21 to 47 tok/s.

    Read More I Ran Qwen3-Coder 30B on an AMD RX 9070 XT — 47 tok/s, No ROCm RequiredContinue

Page navigation

Previous PagePrevious 1 2 3 4

© 2026 MoonWork Lab — every number measured on hardware I own.
About · Contact · Privacy · Affiliate Disclosure

  • Local LLM & GPU
  • AI-Assisted Dev
  • Hardware & Desktop
  • Self-Hosting
  • About
  • Contact